The Workstation Blog
LLM
Posts tagged LLM.
Muse Glimmer on Ollama: Always-On Local Agents on One GPU
Meta Muse Glimmer brings always-on local agents to a single GPU via Ollama: 30B, Apache 2.0, 128K context, vision and tools — Workstation business guide.
 WorkstationRead
Large Language Models Explained: How LLMs Work and How to Run Your Own on Kubernetes
What are Large Language Models and how do they work? A clear, non-technical explainer for managers and engineers — tokens, embeddings, transformers, training and inference — plus production Kubernetes YAML to deploy your own LLM with Ollama and vLLM.
WorkstationRead 
KubePilot: CoPilot, Pilot & AutoPilot for Faster Kubernetes Incidents
KubePilot helps SRE, DevOps, and platform teams move from noisy cluster signals to a safe fix — CoPilot, Pilot, and AutoPilot. Open source at kubepilot.org.
WorkstationRead 
Kimi K3 & Open Weights: Frontier Agents Without Locked-In APIs
Kimi K3 pushes open-weight models into frontier agent territory. What changed for developers, vLLM serving, MCP, and Workstation production advice.
WorkstationRead 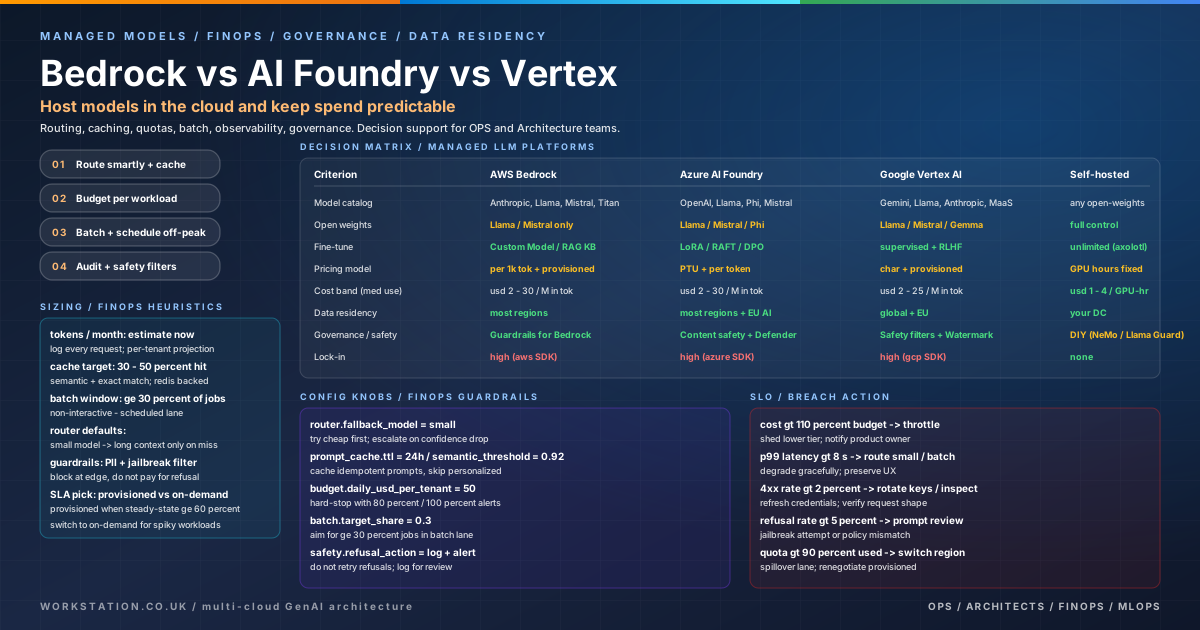
Hosting AI Models on AWS Bedrock and Azure AI Foundry: Cost Control That Scales
Run production AI on AWS Bedrock and Azure AI Foundry with clear patterns for model choice, caching, batching, quotas, and FinOps—so innovation does not blow the cloud bill.
WorkstationRead 
Claude Opus 5 on AWS: Workstation Guide for Builders & Business
Workstation take on Claude Opus 5 on Amazon Bedrock: agentic coding, long-running agents, 1M context, ZDR by default, and how teams should adopt it.
WorkstationRead 
Claude Models Compared: Haiku vs Sonnet vs Opus vs Fable 5 (Mythos 5)
Choose the right Claude model tier: Haiku for fast routing, Sonnet for daily work, Opus for complex agentic coding, and Fable 5 for long-horizon autonomy. Includes a token-budget router blueprint.
WorkstationRead 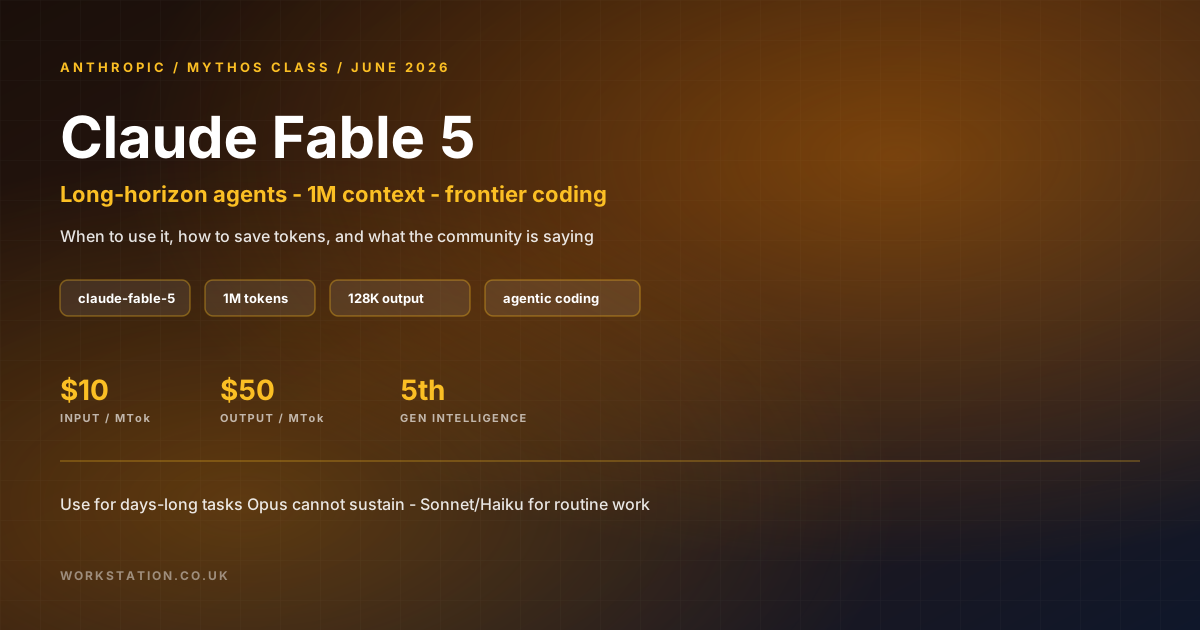
Claude Fable 5: The Complete Guide to Anthropic's Mythos-Class Model
Claude Fable 5 is Anthropic's Mythos-class frontier model for long-horizon agents. Community reactions, YouTube reviews, when to use it, and how to save tokens.
WorkstationRead