The Workstation Blog
MLOps
Posts tagged MLOps.
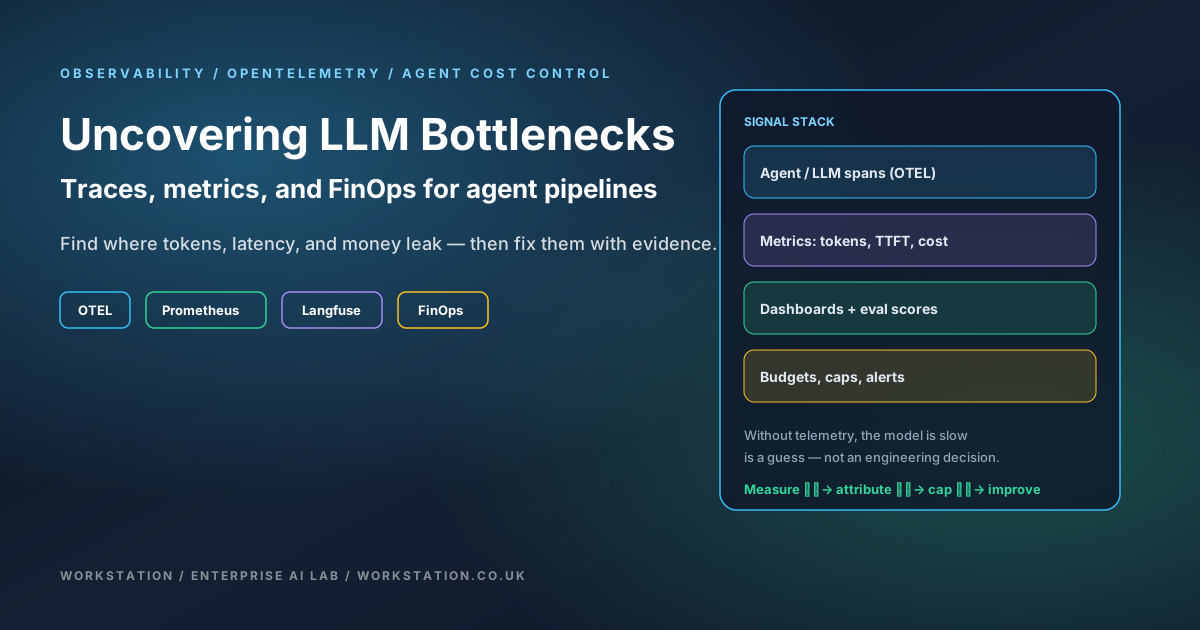
Uncovering LLM Bottlenecks: Observability, OTEL & Cost Control
Workstation on uncovering LLM agent bottlenecks with observability: OpenTelemetry, Prometheus/Grafana/Thanos, Langfuse — with clear pros/cons, cost levers, and usage metrics that protect margins.
 Balinder WaliaRead

Turbocharging LLMs
Workstation on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Balinder WaliaRead 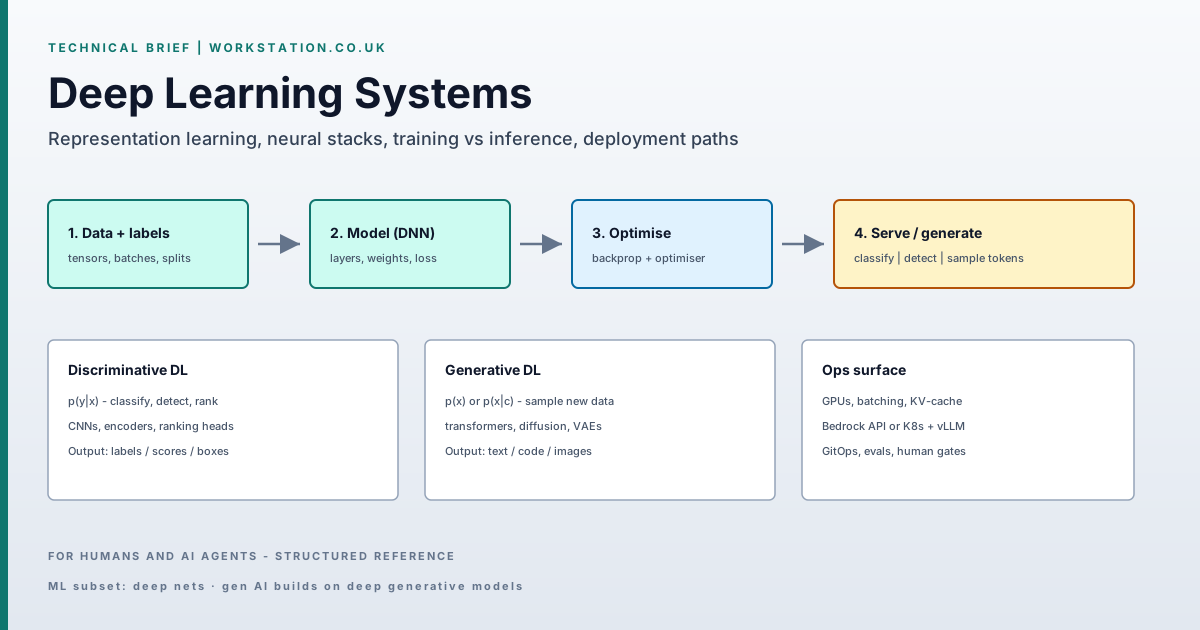
Deep Learning Systems: Technical Brief for Engineers & Agents
Technical Workstation brief on deep learning: gradient-trained deep nets, discriminative vs generative models, task metrics, and Bedrock vs Kubernetes serving.
WorkstationRead 
Large Language Models Explained: How LLMs Work and How to Run Your Own on Kubernetes
What are Large Language Models and how do they work? A clear, non-technical explainer for managers and engineers — tokens, embeddings, transformers, training and inference — plus production Kubernetes YAML to deploy your own LLM with Ollama and vLLM.
WorkstationRead 
Kubeflow + Argo CD: GitOps MLOps on Kubernetes
Pair Kubeflow and Argo CD for MLOps on Kubernetes: train and register models in Kubeflow, promote InferenceServices with GitOps, roll back with git revert.
WorkstationRead